
Pre-Winter Sale Limited Time 75% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code = simple75
Pass the Microsoft Certified: Fabric Analytics Engineer Associate DP-600 Questions and answers with Dumpstech
What should you use to implement calculation groups for the Research division semantic models?
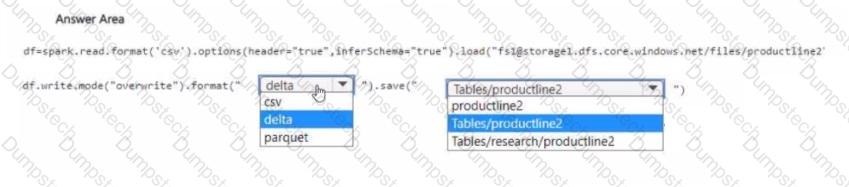
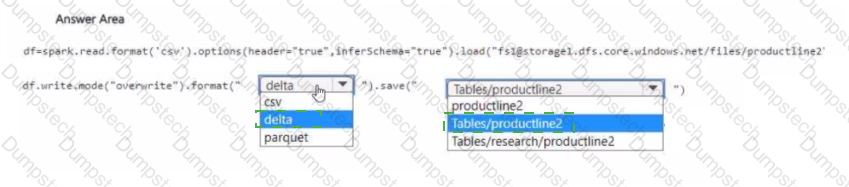
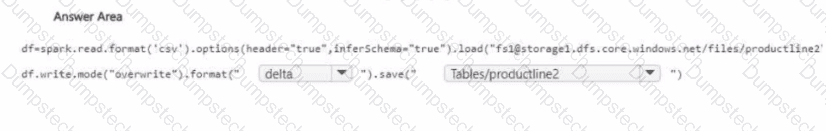
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area
NOTE: Each correct selection is worth one point.
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 uses Pro license mode and contains a semantic model named Model1. You need to ensure that Modell supports XMLA connections. Which setting should you modify?
You have a Fabric tenant that contains a lakehouse.
You plan to query sales data files by using the SQL endpoint. The files will be in an Amazon Simple Storage Service (Amazon S3) storage bucket.
You need to recommend which file format to use and where to create a shortcut.
Which two actions should you include in the recommendation? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
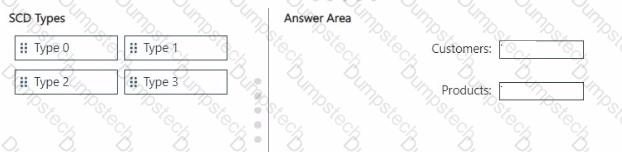
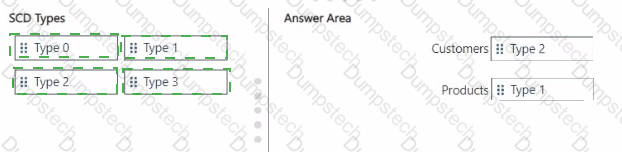
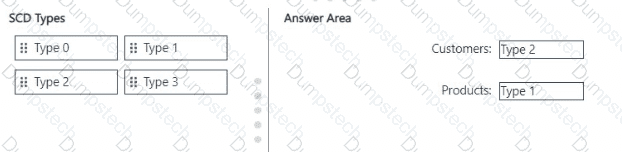
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of data. The solution must meet the requirements shown in the following table.
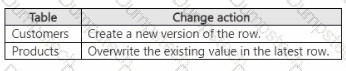
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes o r scroll to view content.
NOTE: Each correct selection is worth one point.
You have a Fabric tenant that contains a new semantic model in OneLake.
You use a Fabric notebook to read the data into a Spark DataFrame.
You need to evaluate the data to calculate the min, max, mean, and standard deviation values for all the string and numeric columns.
Solution: You use the following PySpark expression:
df.show()
Does this meet the goal?
You have a Fabric warehouse that contains a table named Staging.Sales. Staging.Sales contains the following columns.
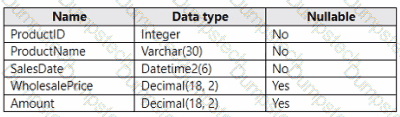
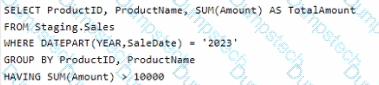
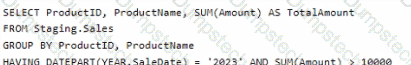
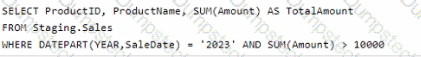
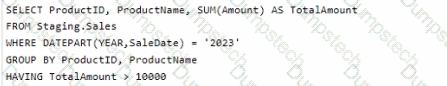
You need to write a T-SQL query that will return data for the year 2023 that displays ProductID and ProductName arxl has a summarized Amount that is higher than 10,000. Which query should you use?
A)
B)
C)
D)
You have a Fabric tenant that contains the workspaces shown in the following table.
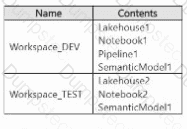
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
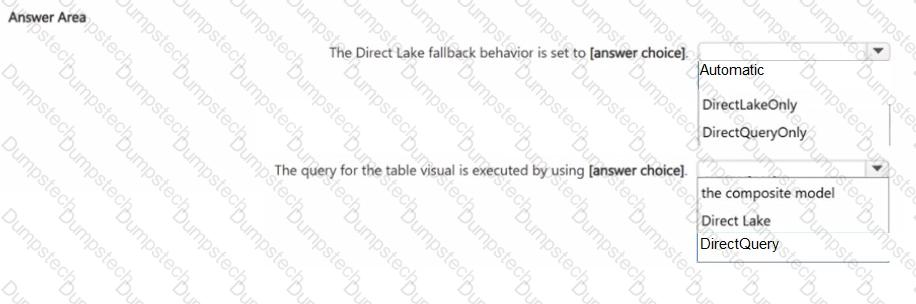
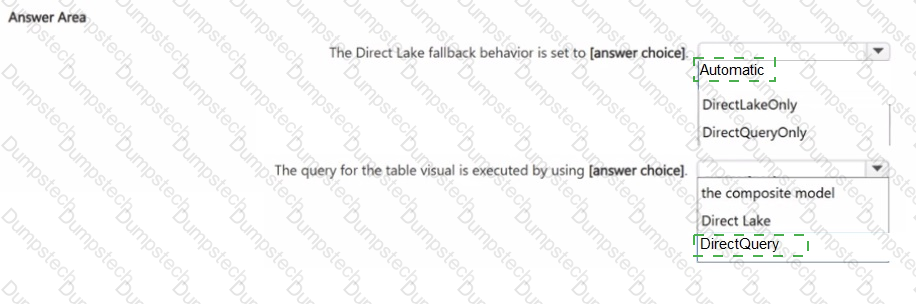
You have a Microsoft Power Bl report and a semantic model that uses Direct Lake mode. From Power Bl Desktop, you open Performance analyzer as shown in the following exhibit.
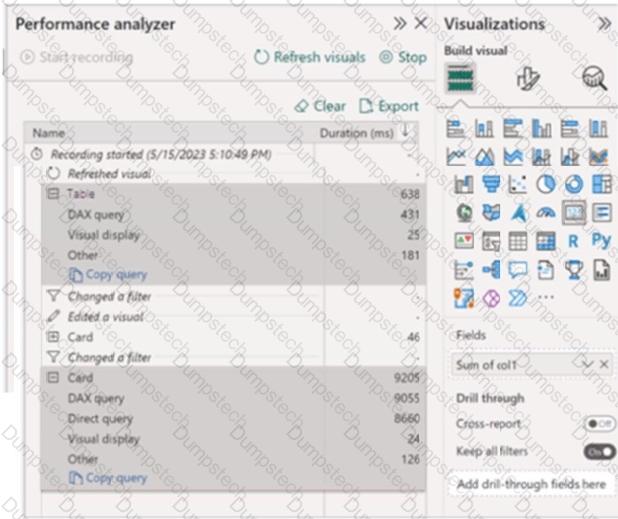
Use the dropdown menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
You have a Fabric workspace named Workspace-!. You have a GitHub repository named Repol. You need to connect Workspacel to the main branch of Repol. Which information should you provide?
Q A. an access key and the URL of Repo1
(§) B. a personal access token (PAT) and the URL of Repo1
Q C. an access key and the branch name of Repo1
Q D. a shared access signature (SAS) token and the branch name of Repo1
